Anthropic Adds Plugin A/B Testing to Claude Code
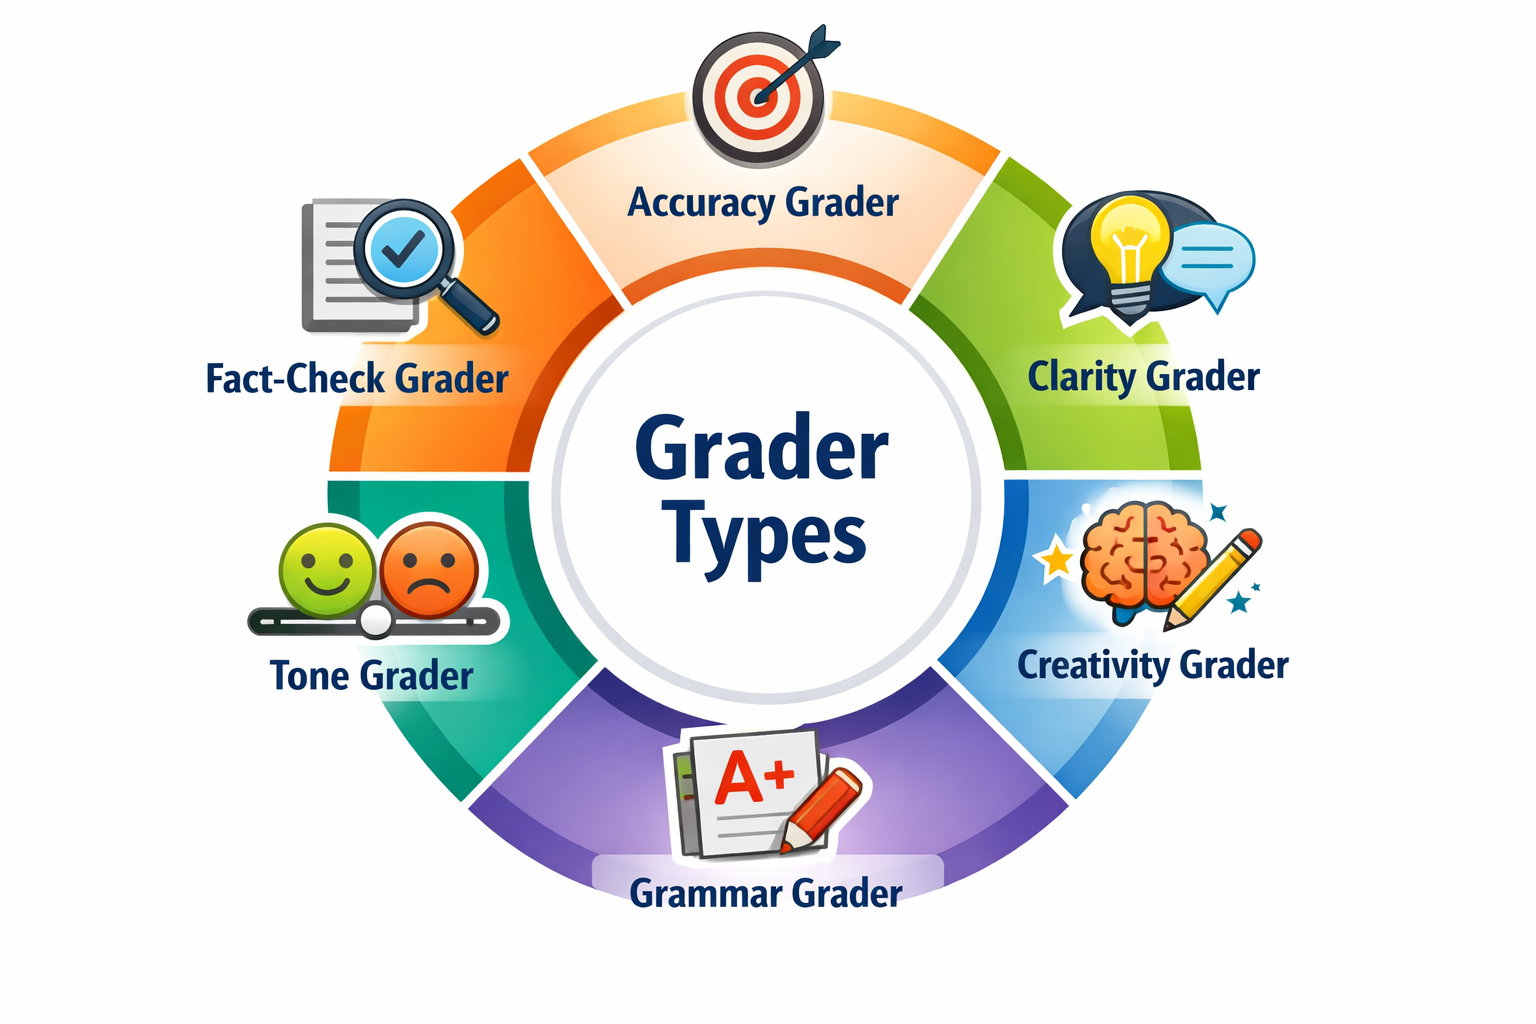
Anthropic released a comprehensive plugin evaluation framework for Claude Code on September 11, 2026, introducing the claude plugin eval command that runs a plugin against realistic prompts, grades what Claude produced, and compares the result with a run where the plugin is not loaded. The evaluation workflow includes six grader types, a no-plugin baseline for comparison, and a continuous integration gate for skill assessment. This marks a significant development for teams building extensions and agent skills on the Claude Code platform.
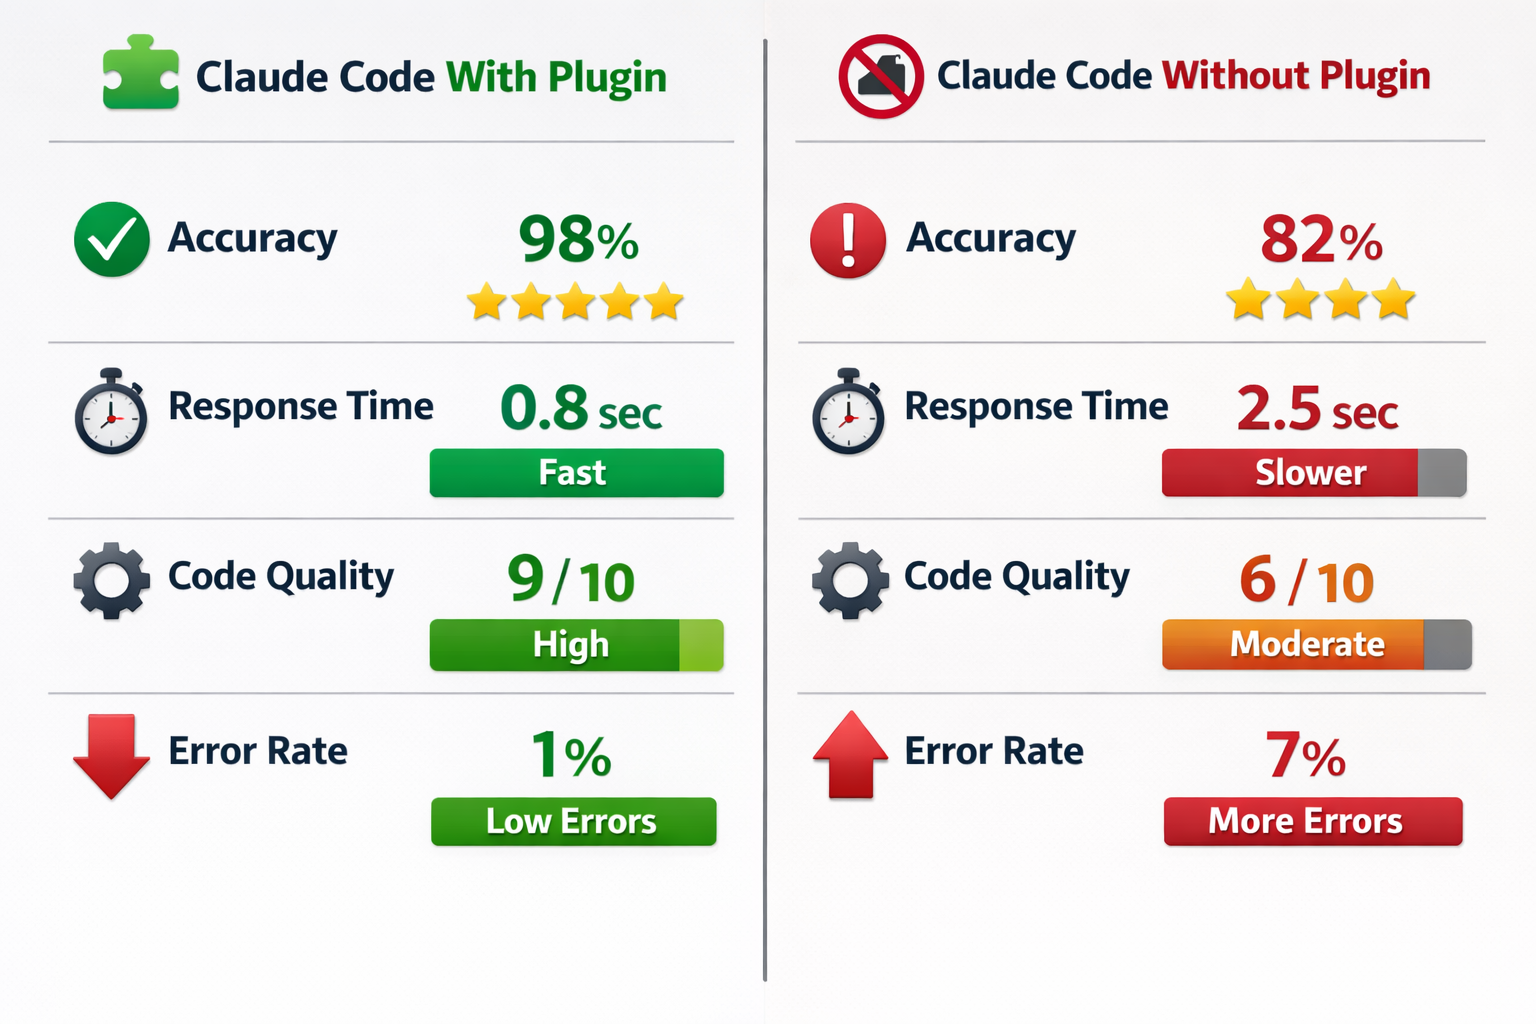
The new evaluation system provides developers with a built-in A/B test for Agent Skills and Claude Code plugins, run entirely from your terminal. According to documentation released alongside the feature, the plugin-evals page covers eval suite setup, requirements, graders, baseline comparisons, custom eval directories, tool grants, mocked MCP servers, JSON/HTML results, and CI usage.
How the Plugin Evaluation Framework Works
The claude plugin eval command produces scored, reproducible results in both JSON and HTML report formats, allowing developers to quantify the impact of their plugins on Claude Code’s performance. The workflow addresses a common challenge in AI agent development where teams traditionally relied on anecdotal evidence to assess plugin effectiveness.
The eval suite lives alongside the plugin it tests, not in a separate repo, streamlining the development process. Developers can initialize evaluation suites with a simple command structure, and the system automatically compares plugin-enabled performance against baseline runs without the plugin loaded.
The framework supports multiple grader types that assess different aspects of plugin behavior, from output quality to task completion accuracy. This multi-dimensional scoring approach helps developers identify specific areas where their plugins add value or require refinement.
Broader Claude Code Updates
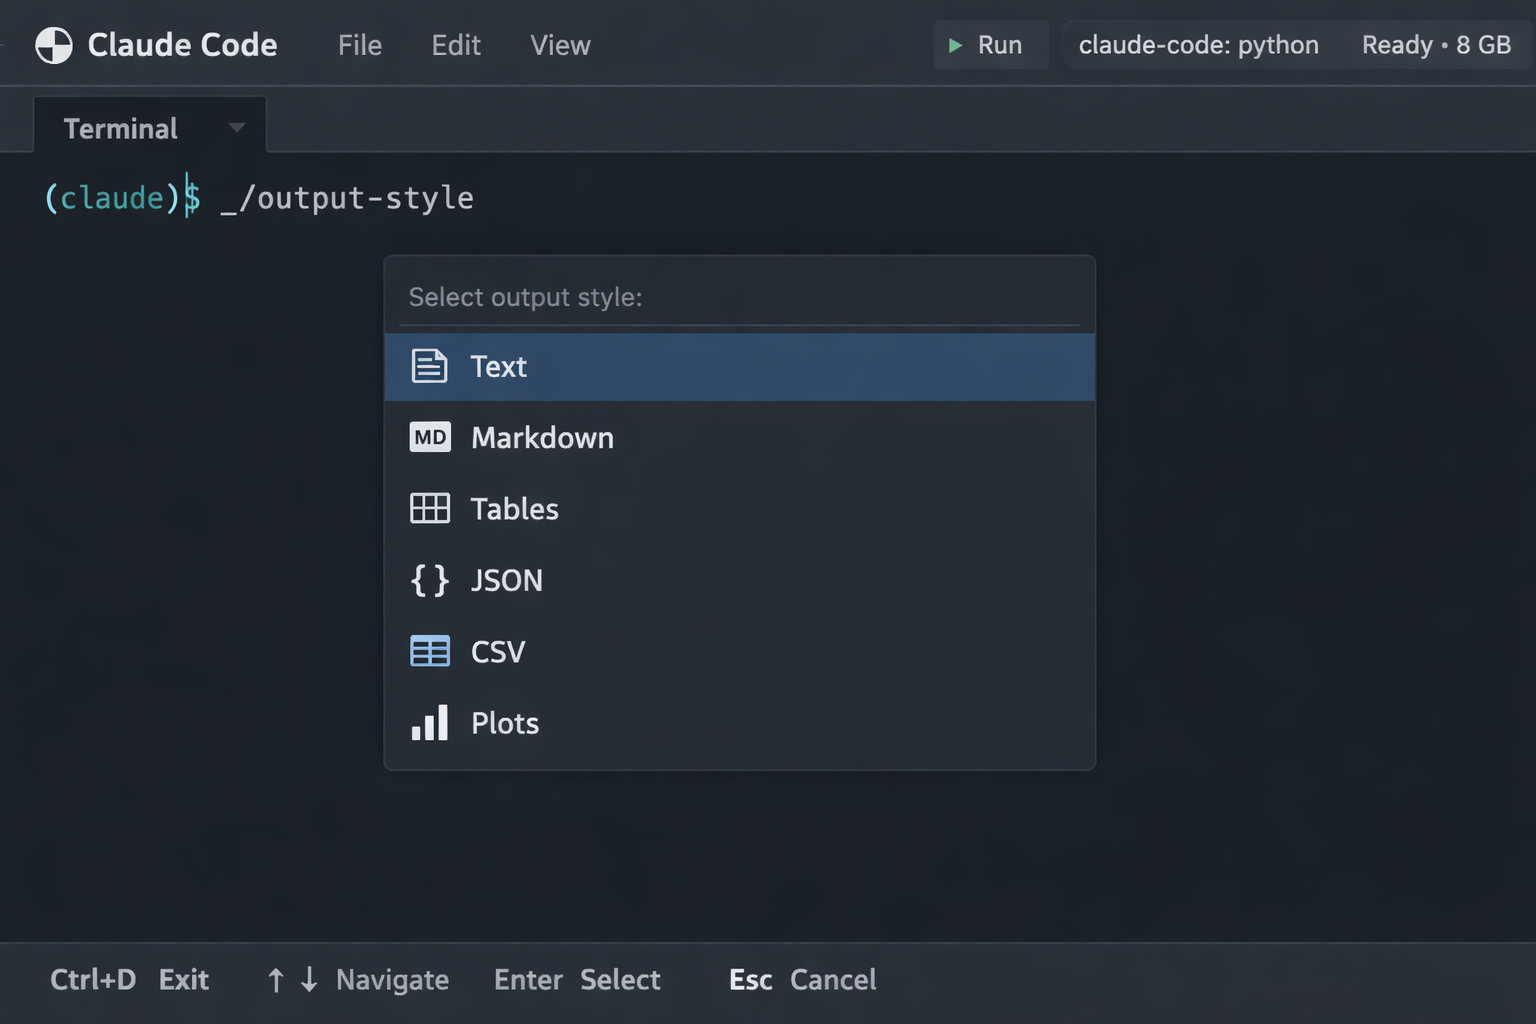
The plugin evaluation framework arrived as part of a larger Claude Code release that included several workflow and reliability improvements. Version 2.1.269 added /output-style [name] to list and switch output styles, including over Remote Control and in cloud and other headless sessions.
Additional updates in the September 11 release addressed session management, terminal functionality, and prompt caching. The default model for seat-based Enterprise subscriptions changed to Opus 5, matching other premium plans, and the system now saves default effort levels per model, allowing each model to maintain its own setting when users switch between them.
Claude Code gained plugin evals as the first native A/B testing framework for agent skills, positioning the platform as a more robust development environment for AI-assisted coding workflows.
Enterprise Adoption and Analytics
Parallel to the Claude Code updates, Anthropic expanded enterprise features across its product line. Smart Reports entered beta on Enterprise plans, giving teams native analytics for Claude adoption and spend. This addition provides organizations with visibility into how their teams use Claude services and associated costs.
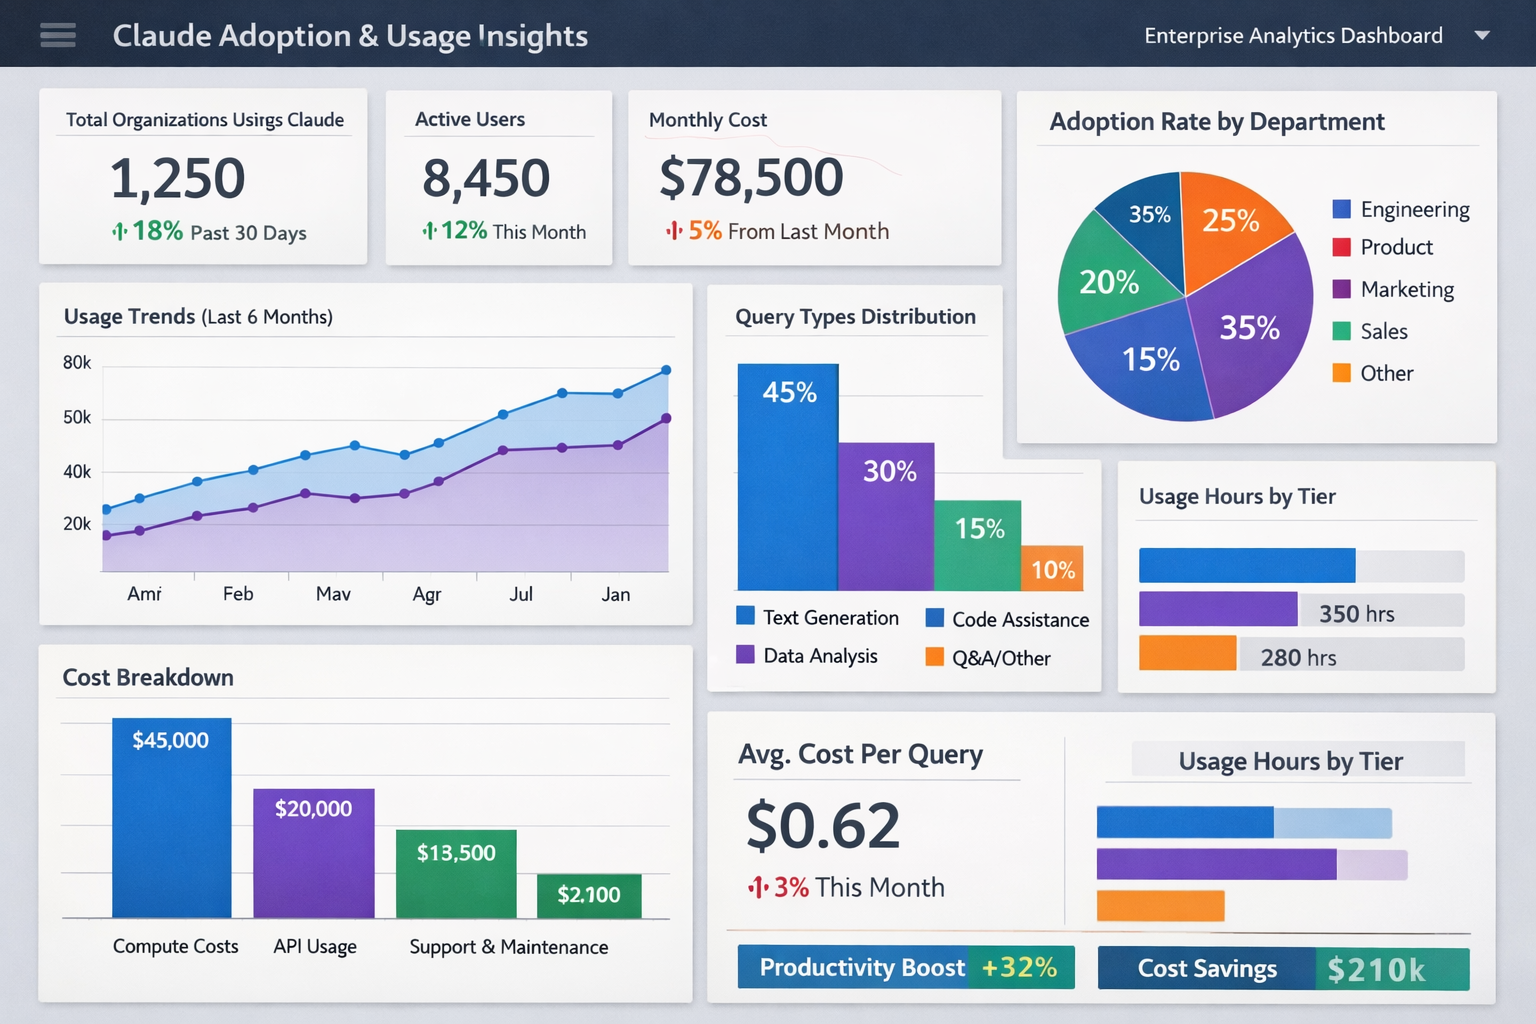
Enterprise adoption of Claude continues to expand in financial services. Sony Bank and Fujitsu announced broader use of generative AI in core banking system development, incorporating Claude and Claude Code on Amazon Bedrock. The deployment spans design documents, source code generation, and test asset creation, reflecting growing confidence in AI-assisted development for mission-critical systems.
Security and Misuse Mitigation
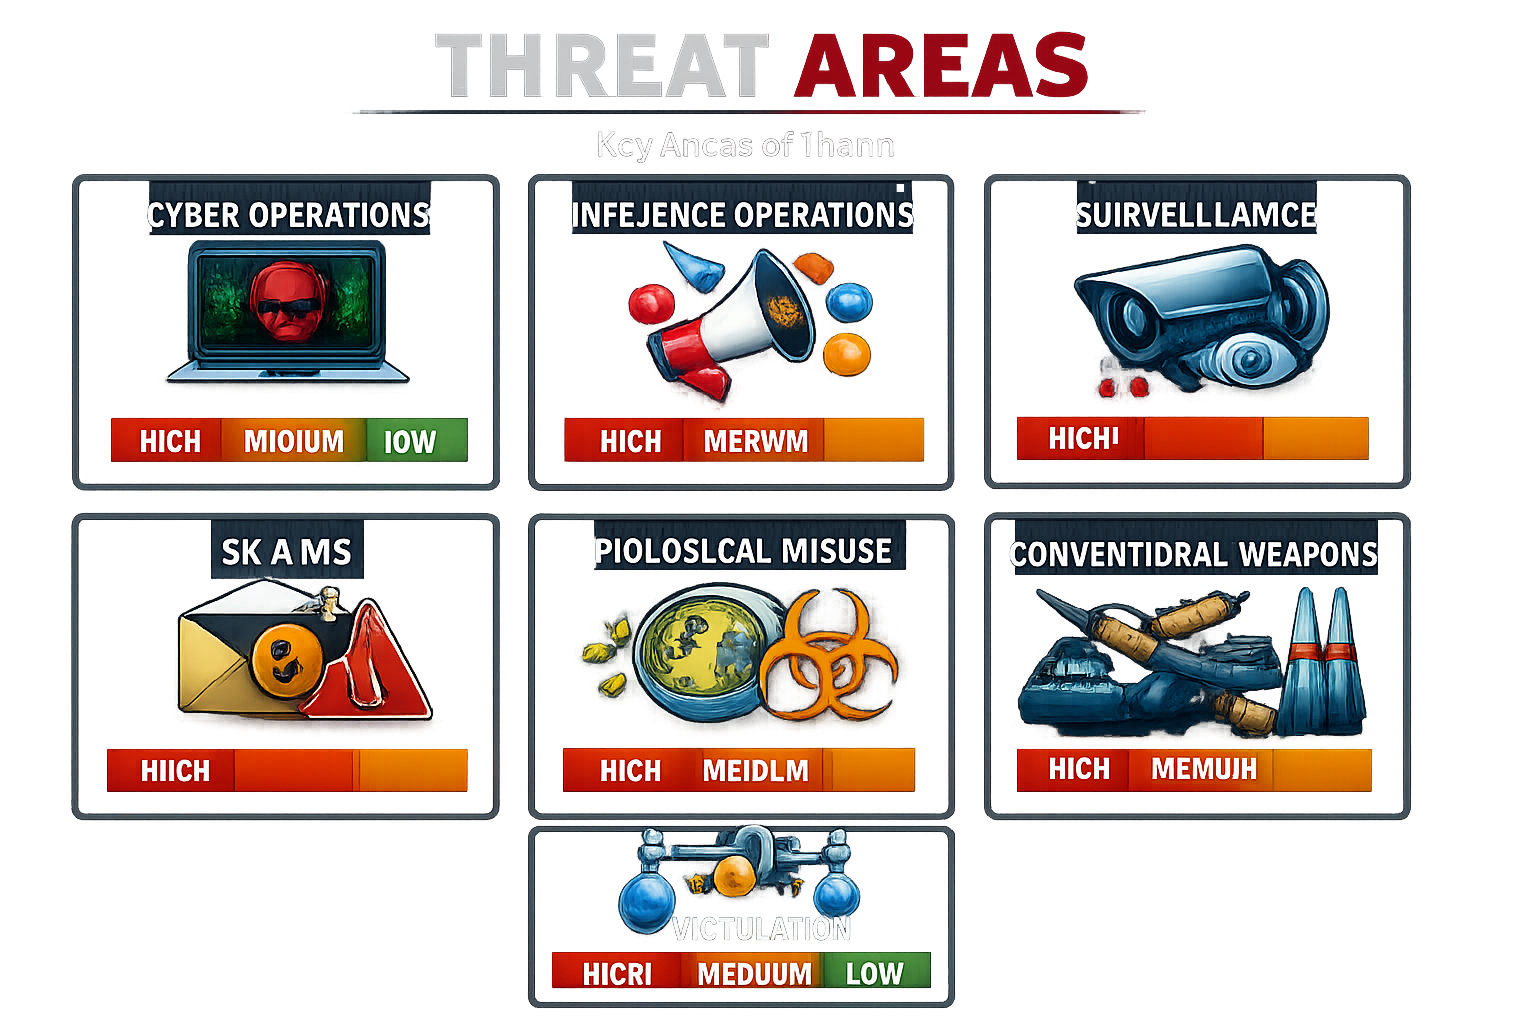
Alongside the technical releases, Anthropic published its most detailed threat intelligence report on September 10, covering misuse disrupted from December 2025 to August 2026 across seven harm areas: cyber operations, influence operations, surveillance, scams, biological misuse, conventional weapons, and distillation.
The report documented significant misuse attempts, including large-scale model distillation attacks. Alibaba ran the largest distillation attack Anthropic has ever measured: 151 million exchanges routed through Claude to train Alibaba’s models. The report also detailed disrupted cyber espionage campaigns and attempts to use Claude for weapons research.
Key Facts
- Release Date: Claude Code plugin evaluation framework launched September 11, 2026
- Core Feature: claude plugin eval command provides JSON and HTML scoring reports comparing plugin-enabled versus baseline performance
- Evaluation Components: Six grader types, no-plugin baseline comparison, and continuous integration support
- Enterprise Updates: Smart Reports analytics entered beta for Enterprise plans
- Security Report: Threat intelligence covering December 2025 to August 2026 published September 10, documenting 151 million distillation attempts by Alibaba
- Model Changes: Opus 5 now default for seat-based Enterprise subscriptions
Implications for Developer Workflows
The plugin evaluation framework addresses a critical gap in AI agent development tooling. Previously, developers lacked standardized methods to measure whether custom plugins genuinely improved Claude Code’s performance on specific tasks. The new system provides quantifiable metrics that can inform plugin refinement and justify development investment.
The CI integration capability allows teams to incorporate plugin evaluation into automated testing pipelines, preventing regressions and ensuring plugins maintain quality standards as they evolve. Combined with the detailed HTML reports, the framework supports both technical validation and stakeholder communication about plugin effectiveness.
As AI coding assistants become more prevalent in enterprise software development, standardized evaluation methodologies help organizations make informed decisions about which extensions to deploy and maintain. The framework’s baseline comparison approach directly answers the question of whether a plugin provides measurable value beyond Claude Code’s native capabilities.
Sources
- Anthropic Adds Plugin Evals to Claude Code – MarkTechPost
- Plugin Eval Docs and 2.1.269 Release Notes – GitHub
- Claude Weekly: Plugin Evals Ship, Threat Report Names Names – Big Hat Group
- Sony Bank and Fujitsu Apply Generative AI to Core Banking System – JCN Newswire
Sources
- Anthropic Adds Plugin Evals to Claude Code: 6 Grader Types, a No-Plugin Baseline, and a CI Gate for Skills – MarkTechPost
- Google TimesFM-3 forecasting model; Anthropic adds plugin evaluation framework for Claude Code | gekro
- claude plugin eval: Score Your Claude Code Plugin | explainx.ai Blog | explainx.ai
- Release Plugin Eval Docs and 2.1.269 Release Notes · llms-txt-archive/anthropic-claude-code
- Anthropic Release Notes – September 2026 Latest Updates – Releasebot
- Claude Code Updates by Anthropic – September 2026 – Releasebot
- Claude Weekly: Plugin Evals Ship, Threat Report Names Names | Big Hat Group Inc.